Agent task execution
A Task run combines the Task, its assigned Agent, and an eligible Runtime on a connected Computer. Anakin coordinates the run while the Task remains the shared record for People and Agents.
How an initial run starts
The normal path is:
- A person creates or updates a Task.
- The Task is assigned to an Agent or Crew through the Assignee control.
- Anakin checks the Task status category and execution readiness.
- An eligible run is queued and dispatched to the selected Computer.
- The local service prepares the task directory and starts the Runtime.
- Progress, trace events, and the result return to the Task.
A Task assigned to an Agent or Crew does not start an initial run while it is in Backlog. Backlog acts as a parking area where work can be prepared before execution. Moving the Task out of Backlog starts the assigned Agent or Crew when the target is ready.
Completed, canceled, and duplicate categories do not start an initial run when the execution assignment changes. A later eligible comment can still start a conversational follow-up on a completed Task.
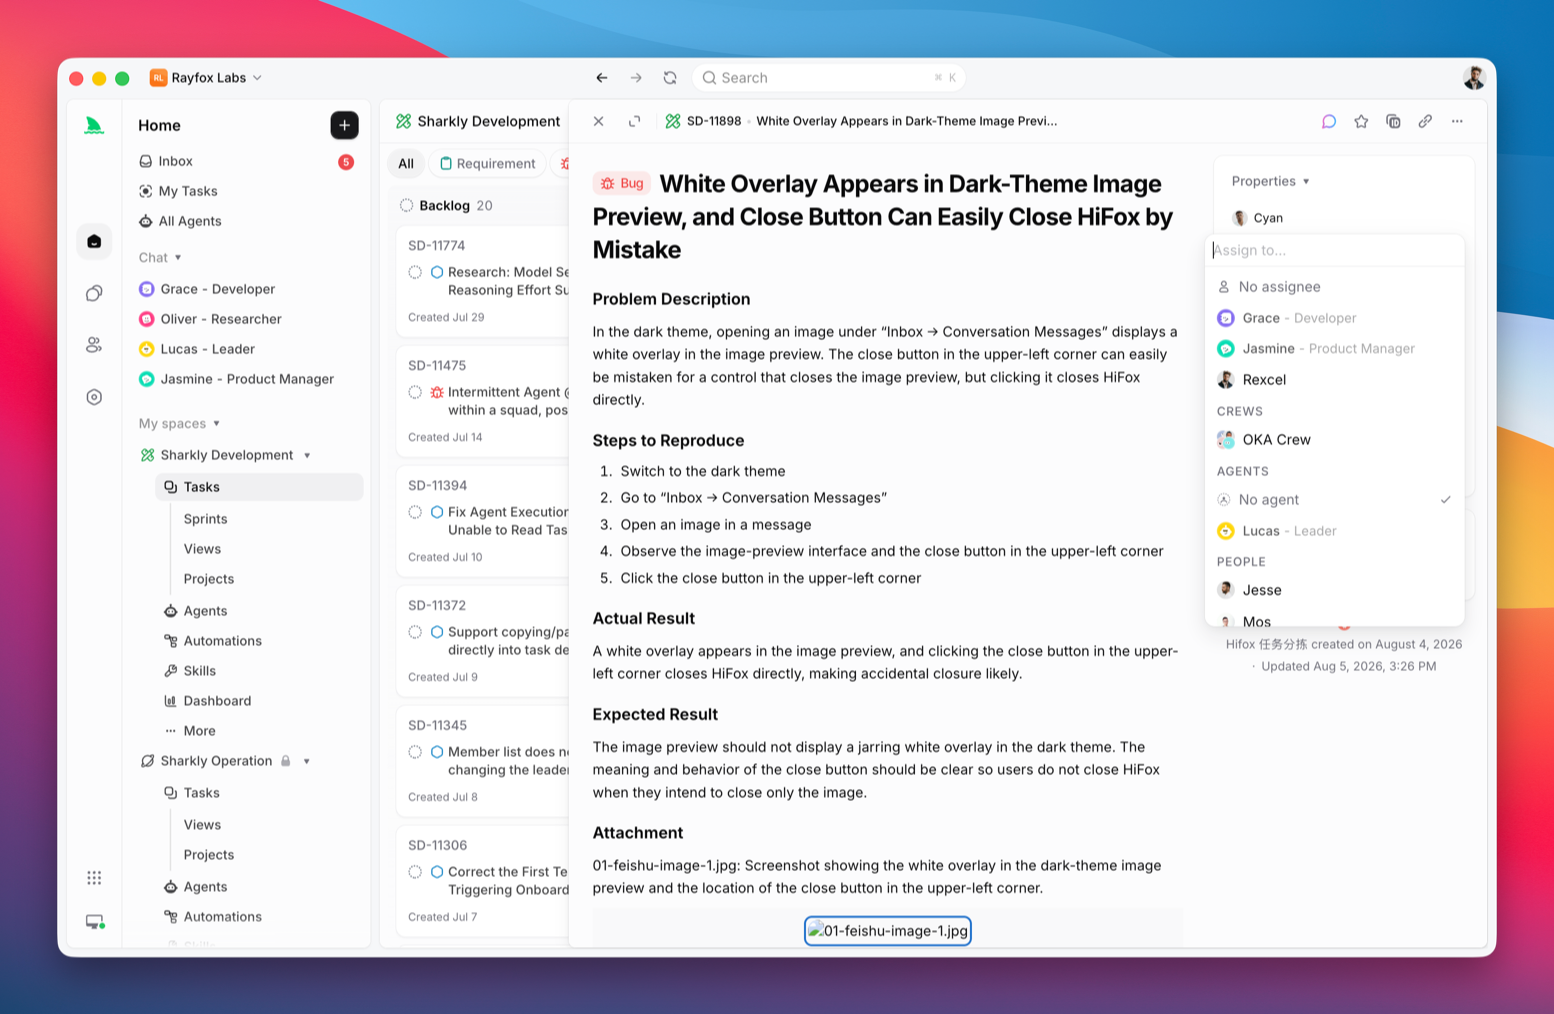
While assigning, you can also pick a model for that run: hover an Agent row in the Assignee picker to reveal the model icon at its end, then open the dropdown and choose a model for this Agent on this task. It overrides the Agent's default model; choosing Default keeps the Agent's own settings. The list, table, board card, and task-detail Assignee pickers all support it.
Context supplied to the run
A task-backed run can include:
- Task title and description;
- current status, priority, Task type, and other properties;
- Space, Project, Sprint, labels, and related identifiers;
- recent comments and the comment that triggered the run;
- the Task type Workflow and the statuses allowed by that Workflow;
- Agent instructions and assigned Skills;
- Agent or Space repositories;
- configured environment variables, secret bindings, and Runtime arguments;
- working-directory and timeout settings.
The Task type Workflow constrains which Task statuses the Agent can select. Run states such as queued or running are separate from Task workflow statuses.
Dispatch and execution
The local service on the Computer receives the run and starts the selected Runtime. Before the Runtime begins, it may need to:
- wait for Computer or Agent concurrency capacity;
- wait for a free specified local directory;
- create a temporary directory;
- fetch or check out configured repositories;
- project the allowed environment and credentials;
- construct the Runtime invocation.
If the Computer disconnects before dispatch, the run can remain queued. A Runtime or directory problem can instead surface as a failed run that needs configuration or reassignment.
While the environment is being prepared, the conversation shows live progress such as cloning a repository, creating a worktree, and checking out code.
Working-directory modes
See Agent working directory for how the two modes differ and for Specified directory exceptions.
Create temporary directory
Each Task gets an isolated directory. Repository-backed work can use a separate worktree for each run, which reduces interference between concurrent Tasks.
Use this mode for most repository work and whenever several Tasks may modify the same codebase in parallel.
Specified directory
The Agent uses a configured absolute directory. When you save a Git folder, choose How should tasks use this folder?:
- Run in isolated worktrees: each Task checks out its own git worktree and does not change the original folder. Tasks can run in parallel. Task results are delivered on
<brand-product-id>-agent/<agent>/<task-identifier>; Agent Chat results are delivered on<brand-product-id>-agent/<agent>/<chat-session-id>. For HiFox, the prefix ishifox-agent; for Anakin, it isanakin-agent. Commits on these branches are authored as the triggering person and the Agent (for example "Jane & Thor"), or the Agent alone when an automation with no human triggers the run; when this machine has no commit email configured, the author email falls back to the platform's noreply address. The committer always comes from this machine's own git config, and includes a platform Co-authored-by trailer by default. The author name, email, Co-authored-by trailer toggle, and local commit-signing guidance can be configured or reviewed in the Agent's Git settings — see Agents. Isolated mode supports one directory. - Run directly in this folder: the run reuses the code, dependencies, caches, and tools already present there instead of preparing a new copy. Only one run uses a given specified directory at a time. You can add more paths after choosing this option.
A non-Git folder can only run directly in the folder. If all configured in-place directories are busy, the run enters the waiting-for-local-directory state. See Specified directory for idle-directory selection and when isolation is available.
Run states
A run can move through these states:
- Queued: accepted and waiting for dispatch capacity.
- Dispatched: claimed and starting on the Computer.
- Waiting for local directory: no configured specified directory is free.
- Running: the Runtime is actively working.
- Completed: the run finished successfully.
- Failed: the run ended with an execution error.
- Canceled: a person or system stop ended the run.
These states appear in the Task execution log and Agent run views. They do not automatically imply that the Task has the same workflow status.
Queued is also shown in task lists, boards, Inbox, and Task detail. When execution starts, it changes to Running; after completion, failure, or cancellation, it updates to the corresponding run result. Agent run state describes execution progress and is separate from the Task's lifecycle status.
If changing a Runtime executable causes the interface to show Restarting and rechecking, this is an intermediate state while the local service verifies the configuration. Do not treat it as a final failure or submit conflicting recovery actions again while it is in progress. Wait for success, an explicit failure, or a timeout; treat it as an error only after an explicit failure, timeout, or failed recheck. After success, refresh the Computer, Machine, and Runtime information before continuing or retrying.
Why a run shows Queued
Queued in a conversation or on a Task means the run exists, but no Computer has started it yet. The line below it says what the run is waiting for:
The Queued notice itself is a live card with the reason, the details, and a shortcut to the matching settings: with Agent or Computer concurrency full it shows that concurrency limit and Settings opens the Agent run settings or the Computer settings at the concurrency item; with the Computer's load average too high or available memory below the reserve threshold it shows the load policy or the minimum-memory threshold, with the same shortcut. Every scenario also shows the number of running tasks and how many runs are queued ahead, updating live, so you can tell how long the wait is and where to raise the concurrency limit or adjust the load policy.
- Agent concurrency is full: the Agent is already handling as many Tasks or chats as its maximum concurrency allows. The queued run starts when one of them finishes.
- Computer concurrency is full: the Computer is running as many runs as its limit allows. The queued run starts when any run on it finishes.
- System load average is too high: the Computer has system load protection on and its load average is over the protection policy's limit. The queued run starts when load drops (see Computers).
- Available memory is below the reserve threshold: the Computer has memory protection on and available memory is under the configured minimum. The queued run starts when memory frees up.
- The Agent is already working on this Task: a conversation runs one thing at a time. Each conversation keeps its own directory, so one Agent's different conversations on a Task run side by side. A run that belongs to no conversation, and a run on a Crew Task whose members share one Task directory, still wait for the Agent's other runs on that Task. The queued run starts when the run holding it finishes.
- Crew members take turns in a shared directory: when a Crew shares the Task directory between members on the same Computer, those members run one after another on that Task so they don't edit the same code at once. The next member starts when the current one finishes.
- Waiting for a Computer to pick it up: with none of the limits above, a Computer picks the run up within seconds. If it stays here, check that the Computer is online and its client is running.
A queued run doesn't need a retry. It starts on its own once whatever is holding it back finishes. The wait is not unlimited: it is bounded by the Agent's queue timeout (24 hours by default, adjustable in the Agent's run settings); past it, the run is treated as failed and has to be triggered again. Stop the run if you no longer want to wait.
View run history and details
From the run history, open the run-details drawer to inspect the result while keeping the original Task context available. The result details can use the drawer's full-width area, and long output can be scrolled without leaving the Task page. Button names and layout follow the current UI.
Every run also shows its Triggered by — which human set the run in motion. A run handed over from another Agent, or started by an @ mention, traces back up the chain to the person who started it; runs triggered from external channels such as Slack show the external account; a run that truly cannot be attributed to anyone shows System.
The triggerer also decides whose identity and permissions the run executes with: what the Agent can read and write during the run follows the person who triggered it, not the Agent owner. Permissions are still capped at the Agent owner's. Runs triggered from external channels (for example Slack) or by the system still execute with the owner's permissions, and a run whose triggerer has been removed from the Organization is rejected rather than falling back to the owner.
On the Agent Run queue, open a row to see that run's conversation. You do not need to return to the Task first. This is the same kind of details drawer as the one on the Task. If the source is an Automation, the source name is a link.
Results on the Task
Agent text intended for the team is persisted as a Comment and linked to the run. Activity shows those comments. The Agent chat on the task is a separate record; see Chat with an Agent.
Use the execution log or transcript when you need to inspect:
- why a run was queued;
- when it started and ended;
- tool calls and Runtime events;
- the trigger source;
- failure or cancellation details.
Follow-up comments
A later comment starts follow-up Agent work only when it @ mentions an Agent or Crew. Anakin opens or continues that conversation on the Task. Rapid mentions of the same Agent do not create duplicate pending runs for the same Agent and Task.
A plain comment that does not mention an Agent does not start the Assignee. The detailed mention rules are covered in Comments and replies.
Human attention
An Agent can leave its task conversation needing reply or needing review. Failed or blocked work can also surface as an attention item on that conversation.
Waiting-for-reply and waiting-for-review hand-offs raised inside a task conversation surface in the main sidebar's Task Chats module (see Chat with an Agent) — they no longer enter Inbox. Failures and blocked runs still reach the Inbox, and the desktop banner and Slack notification for the conversation starter still go out either way.
From either surface, the responsible person can open the Task, continue in the conversation, review the result, or decide whether to retry or assign the work elsewhere.
Stop, retry, or reassign
A queued or running execution can be canceled. A canceled run does not resume in place, but the Task and its history remain available. Start another run by retrying where the interface offers it, @ mentioning the Agent in a comment, continuing in the task's chat side panel, or assigning the Task to another Agent or Crew.
Before retrying a failed run, open the execution log and follow Troubleshoot a failed run. Match the title and technical details first. Do not treat a single HTTP status as a complete diagnosis.
Troubleshoot a failed run
When a run fails, open the execution log and read the title plus the technical details. The title describes what happened; the details are the original model-service response. Open the matching section below. If nothing matches, stay on this page.
The failed run still offers View help docs and Get help when the cause is unclear.
An HTTP status in the technical details is a clue, not a complete diagnosis:
- 429 can mean the account is sending requests too quickly, or that billing or quota is exhausted. OpenAI often labels both as rate limits; check
error.codein the details. Anthropic 429 can also be a monthly spend cap and may omit Retry-After. - 400 can mean malformed input, a context window overflow, a model that does not accept images, a content-policy rejection, or a spend cap you set.
- 413 is usually an image or attachment that is too large in bytes, not a full conversation token window.
- 403 usually means the key still works, but the model, Organization, or region is not allowed. Do not treat it as a mistyped key first.
- Timeout / 408 / 504 means the request was slow, canceled, or delayed by a gateway. That is not the same as the Computer being offline.
- If the details mention a content policy or a missing model, stay on this page and use the original text. Do not retry the same request immediately.
What to do:
- Match the title in the execution log to a section below.
- If you need help from someone else, copy diagnostics. The packet includes Anakin, the Runtime, this run, the technical details already shown, and the time.
- If you still cannot recover, use Get help.
Vendor references:
- Claude Code error reference
- OpenCode troubleshooting
- OpenClaw triage
- Gemini CLI troubleshooting
- goose known issues
Model service credentials were rejected
The configured model service did not accept the credentials used for this request.
- Ask the Computer owner to check or replace the model-service key or login.
- Confirm this Computer is using an account the Organization still allows, not a stale local cache.
- Retry only after the credentials change. Retrying the same rejected key usually will not recover.
If the details show 403, check model, Organization, and region permissions before changing the key.
Vendor references:
- Claude Code login and authentication
- GitHub Copilot CLI authentication troubleshooting
- OpenCode troubleshooting (auth)
- Gemini CLI troubleshooting (auth)
- OpenAI API error codes
- Anthropic API errors
Model service rate limit reached
The model service is limiting requests from this account or connection.
- Wait. If the technical details include Retry-After, honor it.
- Lower concurrency, or try a less busy Computer.
- Ask the Computer owner to review the service rate limits.
Do not add quota first. Quota exhaustion is the next section.
Vendor references:
Model service quota is exhausted
The account configured for this model service does not have enough remaining quota.
- Ask the Computer owner to review the plan, quota, or spend cap.
- Retry only after quota is restored or a different account is configured.
- Retrying the same failed request will not restore quota.
Do not wait a few seconds and retry. That is a rate limit, not exhausted quota.
Vendor references:
Model service is temporarily busy
The model service is at capacity and cannot handle this request right now. The prompt is usually not the problem.
- Wait and retry, or switch to another available model.
- If 529 or overloaded repeats quickly, wait for the service to recover.
Anthropic 529 means the service is busy. It is not this Computer's own request-rate limit.
Vendor references:
This model is not available
The selected model was not found for this provider or account. This commonly means the model name, provider namespace, account access, or gateway catalog does not match the configured value.
- Check the model name exactly as the provider documents it, including any provider-specific namespace.
- Confirm the account or gateway used by this Computer can access that model.
- Retry after correcting the configuration. Anakin will not change the selected model automatically.
Keep the technical details when asking for help; they identify the provider response without exposing credentials.
Request is too large for this model
The request contains more input than this model can process in one context window.
- Shorten the conversation, or remove some attachments.
- Switch to a model with a larger context window, then retry.
If the details show 413, check image or attachment size first. Do not treat it as a long conversation.
Vendor references:
Image is too large for this model
The model service rejected an image because it exceeds the supported size limit. Typical limits are about 5–20 MB; Anthropic Messages also documents a ~32 MB byte cap.
- Compress the image, or use a smaller one.
- Remove extra screenshots and retry.
This is an image-byte limit, not a conversation token-window overflow.
Vendor references:
The model cannot process image input
The request included an image, but the selected model or endpoint accepts text only, and the service rejected the image. Nothing you did was wrong, and the image is not broken.
- Switch the Runtime and model from the composer to one that explicitly supports image input, then send again.
- To keep the current model for text, configure a separate vision model for it using the setups below.
- If no vision-capable model is available, replace the image with text first: extract it with OCR, or have an image-capable service describe it.
Do not retry the same request. A text-only model will not start seeing images because you retried.
Common setups:
- omp: set
modelRoles.visionto a model confirmed to support images, and configureretry.fallbackChains: omp model roles. - Hermes: choose between native image input and
auxiliary.vision/vision_analyzebased on model metadata, and make sure the vision role is enabled: Hermes vision guide. - OpenClaw: set a dedicated
agents.defaults.imageModel: OpenClaw model configuration. - GLM models (for example glm-5.3): image input is not supported by default. The official recommendation is to handle images with the Vision MCP while the model handles text: Zhipu Vision MCP Server.
The same model name does not guarantee the same capabilities: a model served through a different provider or endpoint may differ in image support. Judge by the exact model ID used by this run, not by the Runtime name ("Claude Code cannot see images" is usually wrong).
If the error says the image is too large, that is a different problem. See Image is too large for this model.
Vendor references:
Couldn't reach the model service
The configured model service could not be reached.
- Check the Computer's network path to the model service, including proxy and certificates.
- If the Agent uses a local Runtime, also confirm the local service is online. See Computers.
- Retry after connectivity recovers.
A request timeout, a canceled run, or a 504 is not the same as the Computer being offline.
Vendor references:
Model service rejected this request
The request contains an input or option that this model service does not support.
- Check the model and request options, such as unsupported parameters or formats.
- Remove experimental flags or custom parameters and retry.
If the details say the model cannot process images, see The model cannot process image input. If the details mention a content policy or a missing model, return to Troubleshoot a failed run and use the original text. Changing request options alone will not fix those cases.
Vendor references:
The isolated copy of your directory could not be created
The run was set to work in an isolated copy (worktree) of a directory you specified, and that copy could not be created. The run stopped before it changed anything in your directory.
- In the failed run's explanation, choose Switch to run directly in that directory instead of an isolated copy.
- Retry the run from the task conversation or the execution log.
Running directly in the directory works on your original files, so only one run can use that path at a time, and the Agent writes there directly. To keep using the isolated copy, check that the directory is a git repository with at least one commit and that no other process holds a lock on it.
This MCP server needs the full path to its command
Some runtimes (for example DeepSeek Harness) only start an MCP server from the full path of an executable. When the configured command is a bare name such as cmd, npx, or uvx, the computer first tries to find its full path; when it cannot, the run stops before it starts, and the technical details name the MCP server and the command.
- Find the command's full path on that computer: run
where <command>in Command Prompt on Windows, orwhich <command>in Terminal on macOS. - Open the MCP server's configuration and change
commandto that full path, leavingargsas they are. For example, on Windows change"command": "cmd"to"command": "C:\\Windows\\System32\\cmd.exe"(backslashes are doubled in JSON). - Retry the run from the task conversation or the execution log.
If the command cannot be found, it is not installed on that computer or is not on the PATH the runtime sees. Install the tool first (for example, npx comes with Node.js), then fill in its full path as above.